Structured Outputs Under the Hood: How Constrained Decoding Works
How grammar-constrained decoding masks logits to force valid JSON, built from scratch in Python, and the failure modes a schema can't catch.
Share this post
On this page
- The Problem & Context
- Deep Dive / Architectural Design
- Decoding is choosing from a vector of scores
- From JSON Schema to an automaton
- The tokenizer alignment problem
- Making the mask cheap
- What the providers give you
- Hands-On Implementation
- A vocabulary with multi-character tokens
- A toy model with habits
- The grammar: a character-level state machine
- The decoding loop
- Unconstrained vs constrained
- Precomputing the index
- Validate, then repair
- Production Reality Check
- Field order is a reasoning budget
- Enums close the world
- Unsupported schema features: loud or silent
- Truncation and strings that never end
- Schema-valid is not correct
An extraction job reads contracts and returns JSON with the parties, the start date and the termination notice period in days. It ran for months on "respond only with JSON" plus a regex, and a few responses a day still failed to parse. Then the team turned on strict structured outputs. Parse errors went to zero and the retry code was deleted.
A few weeks later someone in legal noticed that contracts saying "ninety (90) days' notice" and contracts saying "notice as agreed in Annex II" both came back with a number. The first was right. The second was made up: the schema said notice_days: integer, the field was required, and the model had nowhere else to go. The JSON was perfect; the data wasn't. This post explains how both can be true: what constrained decoding does at each step, how engines make it fast and what it can't promise, with a tiny decoder built from scratch.
The Problem & Context
Prompting ("answer only with JSON") works most of the time, which is a bad property for a parser: models add a preamble, a Markdown fence, single quotes. JSON mode guaranteed that the output parses, not its shape. Now every major provider and inference engine offers schema-constrained generation: OpenAI's Structured Outputs (strict: true on a JSON schema format or a function), Anthropic's structured outputs (JSON outputs via output_config.format, plus strict tool use), vLLM's structured_outputs request field, llama.cpp's grammars, and libraries like Outlines. The promise is the same everywhere: the output will match your schema.

Read it again: incorrectly formatted. The guarantee is about format, and the same docs list where even the format breaks: the response is cut off at the token limit, or the model refuses and the refusal wins over the schema. Anthropic adds that string enum values may come back with different capitalization. Google's Gemini docs say it plainly: handle "schema-compliant but semantically incorrect outputs." Constrained decoding removes the syntactic class of failure, perfectly. Everything else is still yours.
Deep Dive / Architectural Design
Decoding is choosing from a vector of scores
At each step a model takes the prompt plus everything generated so far and produces one score, a logit, for every token in its vocabulary: about 50,000 for GPT-2, well over 100,000 for current models. A sampler picks one (argmax, or softmax with a temperature and a random draw), the token is appended, and the loop runs again.
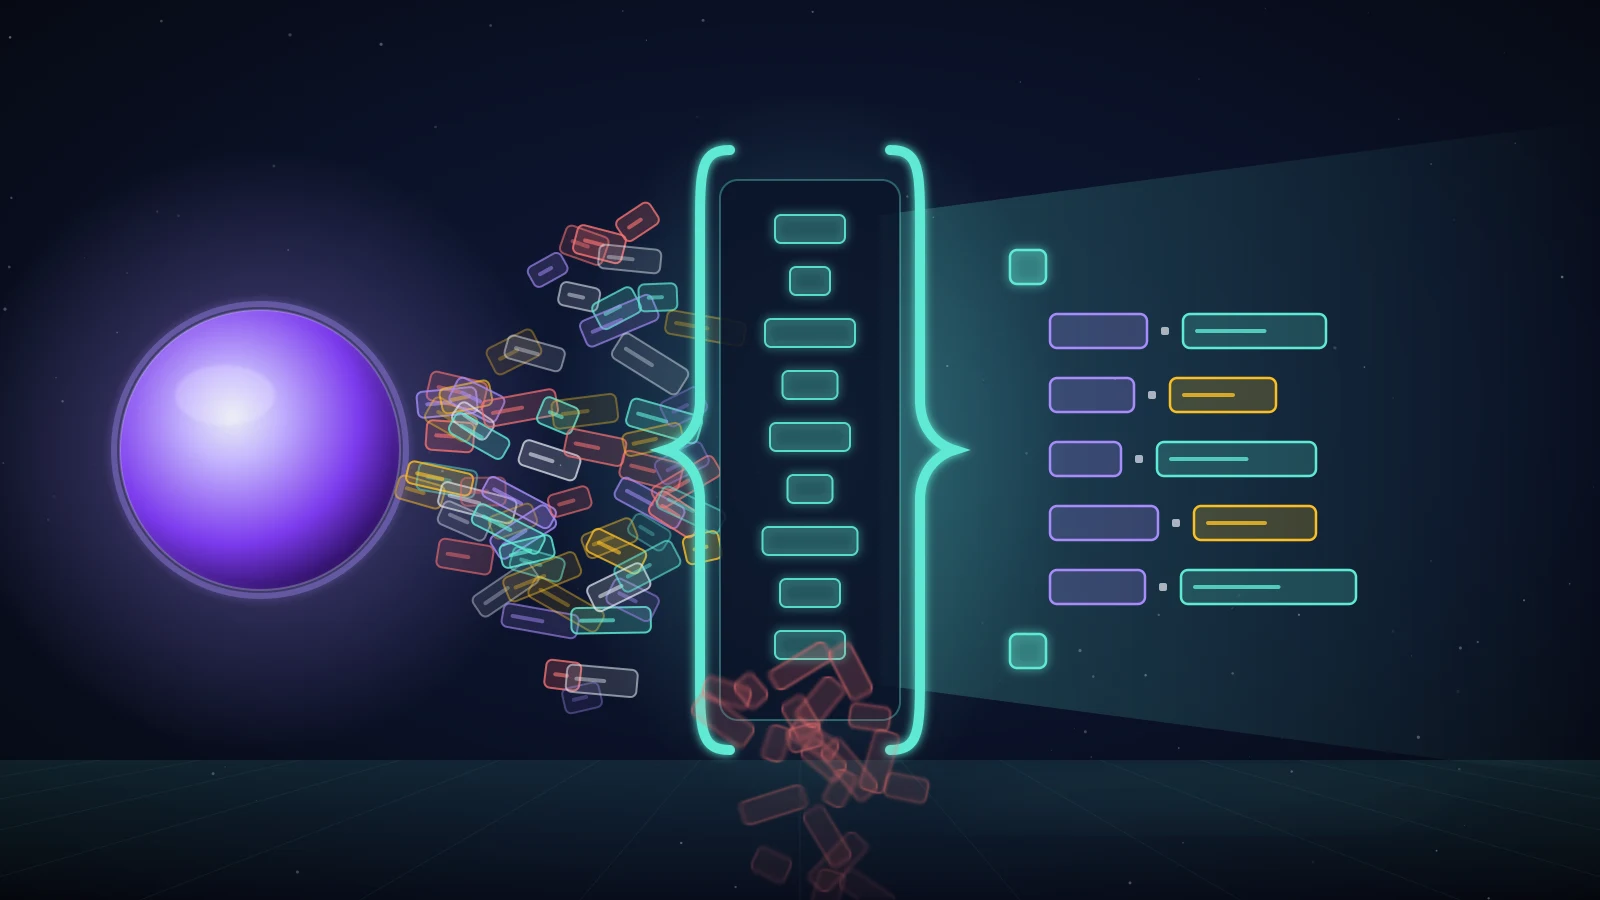
Constrained decoding intervenes at the one place you can without touching the model: between the logits and the sampler. It asks the grammar which tokens are legal next and sets every other logit to minus infinity, so they get probability zero. The model still does all the ranking; the grammar only removes options.
The output is valid by construction: every prefix was valid when extended, and end of sequence is only legal in an accepting state. Among legal tokens the model's preferences are untouched; the interesting behavior happens when what it wanted is illegal.
From JSON Schema to an automaton
The classic reference is Willard and Louf's Efficient Guided Generation for Large Language Models (2023), the paper behind Outlines: generation under a regular expression is a walk through a finite-state machine (FSM), and you can precompute, for every state, the vocabulary tokens that keep the walk alive. A flat schema (a string name and an integer age, in order) is roughly the regex \{"name":"[^"\\]*","age":-?(0|[1-9][0-9]*)\}, whose DFA has finitely many states, so the precomputation terminates.
Nesting breaks that. JSON of arbitrary depth isn't a regular language; matching braces needs a stack. The grammar becomes context-free and the automaton becomes a pushdown automaton (PDA), whose configurations can't all be enumerated in advance. That single fact explains most of the differences between engines.
The tokenizer alignment problem
Grammars are written over characters; models emit multi-character tokens that ignore your grammar's boundaries. The token ": " holds the end of a key, a colon, a space and the opening quote of a string: four grammar events. So an engine checks a token by walking every character through the automaton, and the token is legal only if all of them are.
Subtler: the model was trained on the tokenizer's canonical split, and the grammar doesn't care which split it gets, so it can push the model into one it never saw, such as { then " instead of {". Beurer-Kellner, Fischer and Vechev show in Guiding LLMs The Right Way (2024) that decoders which don't align with the subword vocabulary can significantly hurt accuracy. The toy below does it.
Making the mask cheap
The naive mask walks the whole vocabulary through the automaton on every step, far too slow to run between forward passes. The engines avoid it in different ways:
- Outlines builds an index from each DFA state to its allowed tokens and next states (now in the Rust library outlines-core). Decoding becomes a lookup; the cost moves to compile time.
- XGrammar (Dong et al., 2024) runs a PDA, prechecks and caches the context-independent tokens per position, and checks only the few context-dependent ones against a persistent stack at runtime. The paper reports up to 100x speedups over earlier solutions.
- llguidance (guidance-ai/llguidance) skips heavy precomputation: an Earley parser computes each mask on the fly, about 50 microseconds of CPU for a 128k vocabulary per its README, which lists OpenAI's Structured Outputs, vLLM, SGLang and llama.cpp among its users.
- llama.cpp uses GBNF, a BNF with regex-like extensions, and converts JSON Schema to it. Its README is honest:
minimum/maximumwork only for integers, anduniqueItemsorif/thencan't be expressed at all.
JSONSchemaBench (Geng et al., 2025) tested six frameworks, OpenAI and Gemini included, on 10,000 real-world schemas: keyword coverage varies a lot, and "supports JSON Schema" never means all of it.
What the providers give you
Hosted APIs hide the engine, not its constraints. OpenAI requires every field in required and additionalProperties: false, allows up to 5,000 properties, 10 levels of nesting and 1,000 enum values, rejects keywords like allOf and if/then, and produces keys "in the same order as the ordering of keys in the schema." Anthropic compiles schemas to grammars cached for 24 hours from last use, doesn't support recursive schemas, numeric bounds or string lengths (its SDKs strip them, mention them in the descriptions and validate the response against your original schema), caps each request at 20 strict tools, 24 optional parameters and 16 union-typed parameters, and emits required properties before optional ones.
Hands-On Implementation
The whole mechanism in plain Python: a tokenizer, a toy model, a state machine compiled from a Pydantic schema, the masking loop, an index and a repair loop. Everything ran on Python 3.14 with Pydantic 2.13.5, and every output is copied from those runs.
python -m venv .venv
.venv/Scripts/python -m pip install pydantic
A vocabulary with multi-character tokens
A hand-picked list of merges, the kind BPE learns from JSON-heavy text, plus every printable ASCII character so any string can still be spelled out:
MERGED = [
    "Sure", " Here", " is", " the", " JSON", ":\n",
    '{"', '":', '": ', '": "', '", "', '"}', ", ",
    "name", "age", "Ada", " Lovelace", "Alan", " Turing", "Grace", " Hopper",
    "thirty", "-six", "41", "85", "36",
]
SINGLE = [chr(c) for c in range(32, 127)] + ["\n"]

VOCAB = list(dict.fromkeys(MERGED + SINGLE))
EOS = len(VOCAB)
VOCAB.append("<eos>")
TOKEN_ID = {text: i for i, text in enumerate(VOCAB)}
LONGEST = max(len(t) for t in VOCAB[:EOS])


def encode(text: str) -> list[int]:
    """Greedy longest match, like a BPE tokenizer's preferred split."""
    ids, i = [], 0
    while i < len(text):
        for size in range(min(LONGEST, len(text) - i), 0, -1):
            if text[i : i + size] in TOKEN_ID:
                ids.append(TOKEN_ID[text[i : i + size]])
                i += size
                break
        else:
            raise ValueError(f"no token for {text[i]!r}")
    return ids


def decode(ids: list[int]) -> str:
    return "".join(VOCAB[i] for i in ids if i != EOS)
That's 123 tokens with end of sequence. Tokens like ": " and ", " cross grammar boundaries exactly like real ones.
A toy model with habits
The decoder is the point, so the model is a stand-in you can reason about completely. It has one answer it wants to give, in a chatty format, and two other replies it has seen, including Alan Turing's record. At each step it prefers tokens that continue the longest suffix of the text it recognizes, its own answer most of all; everything else scores by token frequency.
import math
from collections import Counter

from tokenizer import EOS, VOCAB, decode, encode

ANSWER = 'Sure! Here is the JSON:\n{"name": "Ada Lovelace", "age": "thirty-six"}'
HABITS = [
    'Here is the JSON:\n{"name": "Alan Turing", "age": 41}',
    "{'name': 'Grace Hopper', 'age': 85}",
]


class ToyLM:
    """A stand-in model with fixed habits. It wants to say ANSWER. When the text so far
    leaves that script, it realigns on the longest suffix it has seen in any document."""

    def __init__(self, answer=ANSWER, habits=HABITS):
        self.docs = [answer] + habits
        self.prior = Counter(tok for doc in self.docs for tok in encode(doc))

    def continuations(self, text: str) -> list[tuple[int, str]]:
        for k in range(len(text), 0, -1):
            found = [(d, doc[i + k :]) for d, doc in enumerate(self.docs)
                     for i in range(len(doc) - k + 1) if doc[i : i + k] == text[-k:]]
            if found:
                return found
        return [(d, doc) for d, doc in enumerate(self.docs)]

    def logits(self, prompt: str, out: list[int]) -> list[float]:
        # The prompt is ignored: this stand-in decided what it wants to say in advance.
        total = sum(self.prior.values()) + len(VOCAB)
        scores = [math.log((self.prior[tok] + 1) / total) for tok in range(len(VOCAB))]
        for doc, rest in self.continuations(decode(out)):
            bonus = 12.0 if doc == 0 else 8.0
            for tok, piece in enumerate(VOCAB[:EOS]):
                if rest.startswith(piece):
                    scores[tok] = max(scores[tok], bonus + len(piece) * 0.1)
            if rest == "":
                scores[EOS] = max(scores[EOS], bonus)
        return scores
Note that the model knows the right age. It just wants to write it as a word.
The grammar: a character-level state machine
The grammar compiles the schema into segments: literals like { and "name", an optional single space, a string, an integer. A state is (segment index, position inside it), which keeps the machine finite. When a segment can't take a character but is complete, the machine moves on and retries, which is how an integer ends when a } shows up.
from dataclasses import dataclass

from tokenizer import VOCAB

DIGITS = "0123456789"


@dataclass(frozen=True)
class Lit:
    text: str
    start = 0

    def step(self, s, ch):
        return s + 1 if s < len(self.text) and self.text[s] == ch else None

    def done(self, s):
        return s == len(self.text)


@dataclass(frozen=True)
class Space:
    """At most one space: an unbounded run lets a model pad with whitespace until max_tokens."""

    start = 0

    def step(self, s, ch):
        return 1 if s == 0 and ch == " " else None

    def done(self, s):
        return True


@dataclass(frozen=True)
class Str:
    start = "open"

    def step(self, s, ch):
        if s == "open":
            return "body" if ch == '"' else None
        if s == "body":
            if ch == '"':
                return "closed"
            return "body" if ch >= " " and ch != "\\" else None
        return None

    def done(self, s):
        return s == "closed"


@dataclass(frozen=True)
class Int:
    start = "sign"

    def step(self, s, ch):
        if s == "sign" and ch == "-":
            return "minus"
        if s in ("sign", "minus"):
            return "zero" if ch == "0" else "digits" if ch in DIGITS else None
        return "digits" if s == "digits" and ch in DIGITS else None

    def done(self, s):
        return s in ("zero", "digits")


SEGMENTS = {"string": Str, "integer": Int}


def compile_schema(schema: dict) -> tuple[list, list[str]]:
    """A flat object schema to a list of segments, plus the keywords it could not enforce."""
    segs, ignored = [Lit("{"), Space()], []
    for i, (key, prop) in enumerate(schema["properties"].items()):
        if i:
            segs += [Lit(","), Space()]
        segs += [Lit(f'"{key}"'), Space(), Lit(":"), Space(), SEGMENTS[prop["type"]]()]
        ignored += [f"{key}.{kw}" for kw in prop if kw not in ("type", "title")]
    return segs + [Space(), Lit("}")], ignored


class JsonMachine:
    """Character-level automaton. A state is (segment index, position inside it)."""

    def __init__(self, schema: dict):
        self.segs, self.ignored = compile_schema(schema)
        self.start = (0, self.segs[0].start)

    def step(self, state, ch):
        i, s = state
        while i < len(self.segs):
            nxt = self.segs[i].step(s, ch)
            if nxt is not None:
                return (i, nxt)
            if not self.segs[i].done(s):
                return None
            i += 1
            s = self.segs[i].start if i < len(self.segs) else None
        return None

    def accepting(self, state):
        i, s = state
        return self.segs[i].done(s) and all(seg.done(seg.start) for seg in self.segs[i + 1 :])

    def walk(self, state, text):
        for ch in text:
            state = self.step(state, ch)
            if state is None:
                return None
        return state

    def allowed(self, state, vocab=VOCAB) -> dict[int, tuple]:
        """Token id to the state after it. Scans the whole vocabulary: the naive way.
        The last vocabulary entry is end of sequence."""
        nxt = {}
        for tok, text in enumerate(vocab[:-1]):
            after = self.walk(state, text)
            if after is not None:
                nxt[tok] = after
        if self.accepting(state):
            nxt[len(vocab) - 1] = state
        return nxt
walk is the alignment fix in one method: ": " is checked as four grammar events. compile_schema also records the keywords it couldn't enforce, which matters later. Real compilers add nesting, arrays, enums and escapes.
The decoding loop
Greedy decoding with an optional mask: look up (or scan for) the allowed tokens, set the rest to minus infinity, pick the best survivor. trace prints what the model wanted whenever the grammar overruled it. It returns the text, a finish reason (stop or length, like every API) and the token ids.
import math

from tokenizer import EOS, VOCAB, decode


def generate(lm, prompt, machine=None, index=None, max_tokens=40, trace=False):
    """Greedy decoding. With a machine, every step masks the tokens the grammar rejects."""
    out, state = [], machine.start if machine else None
    for _ in range(max_tokens):
        raw = lm.logits(prompt, out)
        logits = raw
        if machine:
            allowed = index[state] if index is not None else machine.allowed(state)
            logits = [x if tok in allowed else -math.inf for tok, x in enumerate(raw)]
        tok = max(range(len(logits)), key=logits.__getitem__)
        if trace:
            wanted = max(range(len(raw)), key=raw.__getitem__)
            note = f"  wanted {VOCAB[wanted]!r}" if wanted != tok else ""
            count = len(allowed) if machine else "-"
            print(f"{len(out):>2}  {VOCAB[tok]!r:<13} allowed={count:<4}{note}")
        if tok == EOS:
            return decode(out), "stop", out
        out.append(tok)
        if machine:
            state = allowed[tok]
    return decode(out), "length", out
Unconstrained vs constrained
import json

from pydantic import BaseModel

from decode import generate
from grammar import JsonMachine
from index import build_index
from lm import ToyLM
from tokenizer import VOCAB, encode


class Person(BaseModel):
    name: str
    age: int


lm = ToyLM()
prompt = "Extract name and age as JSON: Ada Lovelace was thirty-six when she died."

text, finish, _ = generate(lm, prompt)
print(f"unconstrained, finish={finish}\n{text}")
try:
    json.loads(text)
except json.JSONDecodeError as err:
    print(f"json.loads: {err}\n")

machine = JsonMachine(Person.model_json_schema())
index = build_index(machine)
print(f"index: {len(index)} states, vocabulary of {len(VOCAB)}\n")
text, finish, ids = generate(lm, prompt, machine, index, trace=True)
print(f"\nconstrained, finish={finish}\n{text}")
print("json.loads:", json.loads(text))
print("generated:", [VOCAB[i] for i in ids[:4]])
print("canonical:", [VOCAB[i] for i in encode(text)[:4]])$ python demo.py
unconstrained, finish=stop
Sure! Here is the JSON:
{"name": "Ada Lovelace", "age": "thirty-six"}
json.loads: Expecting value: line 1 column 1 (char 0)
index: 29 states, vocabulary of 123
0 '{' allowed=2 wanted 'Sure'
1 '"' allowed=2
2 'name' allowed=2
3 '": "' allowed=4
4 'Ada' allowed=115
5 ' Lovelace' allowed=115
6 '", "' allowed=115
7 'age' allowed=2
8 '": ' allowed=3 wanted '": "'
9 '41' allowed=14 wanted '"'
10 '}' allowed=15
11 '<eos>' allowed=1
constrained, finish=stop
{"name": "Ada Lovelace", "age": 41}
json.loads: {'name': 'Ada Lovelace', 'age': 41}
generated: ['{', '"', 'name', '": "']
canonical: ['{"', 'name', '": "', 'Ada']Unconstrained: a preamble that breaks json.loads at character zero, and the age as a string. Constrained, the trace holds most of this post:
- Step 0. It wanted
Sure; only{and{"are legal. It realigned on Grace Hopper's single-quoted reply, which starts with{, and took{. The last two output lines show the non-canonical split. - Steps 4 to 6. Inside the string 115 of 123 tokens are legal, and the model writes
Ada Lovelace. - Step 8. It wanted
": ", because it was about to write"thirty-six". A quote is illegal for an integer, so it got":. - Step 9. Nothing it has seen continues this text with a digit, so it falls back on token frequency:
41and85are the only number tokens in its documents, one occurrence each, and41wins the tie because it comes first in the vocabulary. The age was decided by token order. - Steps 10 and 11. The text now ends in
": 41, which it has seen in Turing's record, so it follows that record to}and stops.
The result parses, matches the schema, and says Ada Lovelace died at 41.
The grammar did its job: it removed illegal tokens and left the ranking to the model. The preferred continuation was illegal, and the best legal one had nothing to do with Ada Lovelace. That's the mechanism behind "quality loss under constraints": you condition the model on text it wouldn't have written. How much it costs real models is debated. Let Me Speak Freely? (Tam et al., 2024) reported that stricter format constraints degrade reasoning; the Outlines team answered in Say What You Mean that the drop came from prompts and evaluation, not structure. My reading: the damage concentrates where the schema disagrees with how the model wants to express the answer. So make them agree: describe the format in the prompt too, name fields precisely, and give the model a way out when the data isn't there.
Precomputing the index
allowed() scans the vocabulary on every step. build_index does what Outlines does: a breadth-first walk from the start state over every token, recording each reachable state's allowed tokens and where they lead.
from grammar import JsonMachine
from tokenizer import VOCAB


def build_index(machine: JsonMachine, vocab=VOCAB) -> dict[tuple, dict[int, tuple]]:
    """Every state reachable at a token boundary, mapped to {allowed token: next state}."""
    index, todo = {}, [machine.start]
    while todo:
        state = todo.pop()
        if state not in index:
            index[state] = machine.allowed(state, vocab)
            todo += [s for s in index[state].values() if s not in index]
    return index
To see the cost at a realistic size, I exported GPT-2's 50,257 token strings with transformers (one tokenizer.decode([i]) per id, saved as a JSON list) and ran the same machine over them:
import json
import sys
import time

from pydantic import BaseModel

from grammar import JsonMachine
from index import build_index


class Person(BaseModel):
    name: str
    age: int


vocab = json.load(open(sys.argv[1], encoding="utf8")) + ["<eos>"]
machine = JsonMachine(Person.model_json_schema())

t0 = time.perf_counter()
index = build_index(machine, vocab)
build = time.perf_counter() - t0

states = list(index)
t0 = time.perf_counter()
for state in states:
    machine.allowed(state, vocab)
scan = (time.perf_counter() - t0) / len(states)

t0 = time.perf_counter()
for _ in range(1000):
    for state in states:
        index[state]
lookup = (time.perf_counter() - t0) / (1000 * len(states))

sizes = sorted((len(v), s) for s, v in index.items())
print(f"vocabulary: {len(vocab):,} tokens")
print(f"states at token boundaries: {len(index)}")
print(f"index build: {build:.2f} s, {sum(len(v) for v in index.values()):,} entries")
print(f"naive mask, one step: {scan * 1000:.1f} ms")
print(f"index lookup, one step: {lookup * 1e9:.0f} ns")
print(f"smallest allowed set: {sizes[0][0]} tokens at {sizes[0][1]}")
print(f"largest allowed set: {sizes[-1][0]:,} tokens at {sizes[-1][1]}")$ python bench.py gpt2_vocab.json
vocabulary: 50,258 tokens
states at token boundaries: 29
index build: 1.51 s, 54,700 entries
naive mask, one step: 47.4 ms
index lookup, one step: 97 ns
smallest allowed set: 1 tokens at (1, 1)
largest allowed set: 50,122 tokens at (6, 'body')Pure Python on a laptop, so the ratios matter more than the numbers. Scanning costs about 47 ms per token, slower than a small model's forward pass on a GPU. The index makes it a dictionary lookup and moves the price to compile time, 1.5 seconds for two fields: the "first request with a new schema is slower" note from the provider docs, in miniature.
Inside a string, 50,122 of 50,258 tokens are legal, so that mask is almost all ones, and in a nested schema the same state appears under many stacks. That's why a pure FSM index stops scaling and XGrammar separates what the position alone decides from what needs the stack. Real engines apply the mask as a bitmask in one GPU kernel.
Validate, then repair
Constrained decoding hands you text that parses, not data you can trust. The Pydantic model that produced the schema becomes the gate, with the constraints the grammar couldn't enforce and a semantic check no grammar can express: values must be grounded in the source.
import re
from dataclasses import dataclass

from pydantic import BaseModel, ConfigDict, Field, ValidationError, ValidationInfo, model_validator

UNITS = "zero one two three four five six seven eight nine".split()
TENS = {"twenty": 20, "thirty": 30, "forty": 40, "fifty": 50, "sixty": 60, "seventy": 70, "eighty": 80, "ninety": 90}


def numbers_in(text: str) -> set[int]:
    """Digits and simple English number words (thirty-six) that appear in the text."""
    found = {int(d) for d in re.findall(r"\d+", text)}
    for tens, units in re.findall(r"\b(" + "|".join(TENS) + r")(?:-(\w+))?", text.lower()):
        found.add(TENS[tens] + (UNITS.index(units) if units in UNITS else 0))
    return found


class Person(BaseModel):
    model_config = ConfigDict(extra="forbid")

    name: str = Field(min_length=1)
    age: int = Field(ge=0, le=130)

    @model_validator(mode="after")
    def grounded_in_source(self, info: ValidationInfo) -> "Person":
        source = (info.context or {}).get("source", "")
        if self.name not in source:
            raise ValueError(f"name {self.name!r} does not appear in the source text")
        if self.age not in numbers_in(source):
            raise ValueError(f"age {self.age} is not stated in the source text")
        return self


@dataclass
class Failed:
    reason: str
    attempts: list[str]


def extract(source: str, generate, max_attempts: int = 4, budget: int = 8):
    prompt, seen, log = f"Extract name and age as JSON: {source}", set(), []
    for attempt in range(1, max_attempts + 1):
        raw, finish = generate(prompt, max_tokens=budget)
        log.append(raw)
        if finish == "length":
            print(f"attempt {attempt}: cut off at {budget} tokens: {raw!r}")
            budget *= 2
            continue
        if raw in seen:
            print(f"attempt {attempt}: same output as before, giving up")
            return Failed("repeated output", log)
        seen.add(raw)
        try:
            person = Person.model_validate_json(raw, context={"source": source})
        except ValidationError as err:
            problems = "; ".join(e["msg"] for e in err.errors())
            print(f"attempt {attempt}: {raw} rejected: {problems}")
            prompt += f"\nYour previous answer {raw} was rejected: {problems}. Fix it."
            continue
        print(f"attempt {attempt}: accepted {person!r}")
        return person
    return Failed("out of attempts", log)
Each failure gets its own response. Truncation gets a bigger budget. A validation error goes back into the prompt, so the retry has new information. An output identical to one already rejected ends the loop, and the loop ends in a typed Failed, never a guess. generate is any callable; here it wraps the constrained toy decoder:
from pydantic import ValidationError

from decode import generate
from extract import Person, extract
from grammar import JsonMachine
from index import build_index
from lm import ToyLM

source = "Ada Lovelace was thirty-six when she died."
machine = JsonMachine(Person.model_json_schema())
index = build_index(machine)
print("grammar could not enforce:", machine.ignored)

for raw in [
    'Sure! Here is the JSON:\n{"name": "Ada Lovelace", "age": "thirty-six"}',
    '{"name": "Ada Lovelace", "age": "thirty-six"}',
    '{"name": "", "age": 999}',
]:
    try:
        Person.model_validate_json(raw, context={"source": source})
    except ValidationError as err:
        print(" | ".join(e["msg"] for e in err.errors()))


def constrained(lm):
    def call(prompt, max_tokens):
        text, finish, _ = generate(lm, prompt, machine, index, max_tokens=max_tokens)
        return text, finish

    return call


print("\n# the toy model")
print(extract(source, constrained(ToyLM())))

print("\n# a toy that wants to write the age as digits")
print(repr(extract(source, constrained(ToyLM(answer='{"name": "Ada Lovelace", "age": 36}')))))$ python run_extract.py
grammar could not enforce: ['name.minLength', 'age.maximum', 'age.minimum']
Invalid JSON: expected value at line 1 column 1
Input should be a valid integer, unable to parse string as an integer
String should have at least 1 character | Input should be less than or equal to 130
# the toy model
attempt 1: cut off at 8 tokens: '{"name": "Ada Lovelace", "age'
attempt 2: {"name": "Ada Lovelace", "age": 41} rejected: Value error, age 41 is not stated in the source text
attempt 3: same output as before, giving up
Failed(reason='repeated output', attempts=['{"name": "Ada Lovelace", "age', '{"name": "Ada Lovelace", "age": 41}', '{"name": "Ada Lovelace", "age": 41}'])
# a toy that wants to write the age as digits
attempt 1: cut off at 8 tokens: '{"name": "Ada Lovelace", "age": '
attempt 2: accepted Person(name='Ada Lovelace', age=36)
Person(name='Ada Lovelace', age=36)The grammar silently dropped minLength, minimum and maximum, as the Anthropic SDK does, so {"name": "", "age": 999} passes the grammar and only Pydantic stops it. The first attempt hit the token limit: a valid prefix is not valid JSON. The second was schema-valid and wrong, caught only by the grounding check. The toy ignores its prompt, so feedback changed nothing and the loop stopped on the repeat. A model that writes the age the way the schema wants passes on attempt two.
A retry that changes nothing returns the same thing at temperature zero, and at higher temperatures "until something passes" means eventually accepting a wrong answer that happens to pass. Each retry must change an input that matters: the budget, the error in the prompt, the model. When the source doesn't contain the answer, no retry will make it appear. That needs a typed failure and a human.
Production Reality Check
Field order is a reasoning budget
Keys come out in schema order, and each value is conditioned only on what came before it. Put answer first and the model commits before writing anything that could inform it. Put an evidence field first ("quote the sentence that states the notice period") and the answer is conditioned on that quote, which your code can check verbatim against the source. It costs tokens, but it's the cheapest quality lever in the schema. On Anthropic, mark every property required if order matters.
Enums close the world
An enum is the strongest constraint you can write, and a silent data quality problem when the world isn't closed. If a ticket can be billing, bug or feature_request, a security report gets forced into whichever is least wrong. Add an explicit other with a free-text reason and count how often it's used. Compare enum values case-insensitively, per Anthropic's casing caveat.
It can never be invalid. It can be wrong in a way you'll never see, because every wrong answer now looks like a right one. A free-text "notice as agreed in Annex II" is ugly and honest; an enum thirty_days is clean and a lie. Keep enums for things closed by definition, like your supported currencies.
Unsupported schema features: loud or silent
An API that rejects your schema with a 400 is the good case: you find out in development. The dangerous case is a layer that quietly relaxes it, like an SDK moving minimum into a description. The toy printed its ignored list; most real stacks won't. Keep the full schema in your own validator and test edge cases against each engine's documented limits. And compile once per schema: a schema generated per request, like a dynamic enum of this user's projects, defeats every grammar cache.
Truncation and strings that never end
Check the finish reason before parsing: status: "incomplete" with max_output_tokens at OpenAI, stop_reason: "max_tokens" at Anthropic. A related failure is a string that never closes. My first toy model for this post was a trigram model trained on a few replies, one of them single-quoted JSON. Under the grammar it got stuck inside the name, because a single quote is a legal character inside a double-quoted string, and produced this until the 40-token limit:
{"name": "Marie Curie', 'age': 'Marie Curie', 'age': 'Marie Curie', 'age': 'Marie Curie', 'age'The grammar was satisfied at every step and the output was useless. Real models loop too, on content or whitespace, which is why the toy allows at most one space and why maxLength and maxItems are worth setting wherever they're enforced.
Schema-valid is not correct
The grounding check is the most valuable part of the pipeline, and it has nothing to do with decoding. Totals that equal the sum of the line items, IDs that exist in your database, evidence that appears verbatim in the source: no grammar expresses these. It's the argument from Deterministic Tool Calling: the model proposes, your code decides. Structured outputs made the proposal machine-readable, not true.
Constrained decoding does exactly what it says: at every step it removes the tokens that would break your grammar, so the output parses. That's the whole guarantee. It doesn't know whether the model wanted to say something the schema can't hold, whether the response was cut off, or whether the number is true. Let the grammar own syntax, Pydantic own the constraints the grammar dropped, your checks own meaning, and make every retry change something.
Share this post
Related Items
- BlogThe Portuguese Token Tax: 9 Tokenizers, 31 Articles, Same ContentHow much more the same text costs in Portuguese than in English, measured on 31 articles of this site with nine tokenizers, and what to do about it in prompts, budgets and RAG.
- BlogQuantizing LLMs Without Guesswork: What 4 Bits Really CostWhat quantization does to an LLM's weights, activations and KV cache, and how to measure what you lost before you ship it.
- BlogAn LLM-as-a-Judge You Can Trust: Calibrate the Grader Before You Believe the GradeMeasure an LLM judge's position, length and self-preference biases, and its chance-corrected agreement with humans, before its scores drive a decision.
Comments
Questions, corrections, or your own take are all welcome. Sign in with GitHub to join in.