Z.ai
Z.ai's GLM-Legal nearly matches Gemini 4 Argon on legal agent work, at a seventieth of the cost
The legal model, built on GLM-5.3-Flash with reinforcement learning across tens of thousands of legal environments, passes 19.2% of the tasks in Harvey's Legal Agent Benchmark, seventh on Vals AI's leaderboard at 15 cents a task. It is a gated beta for law firms, with no published price and no open weights for now.
Share this news
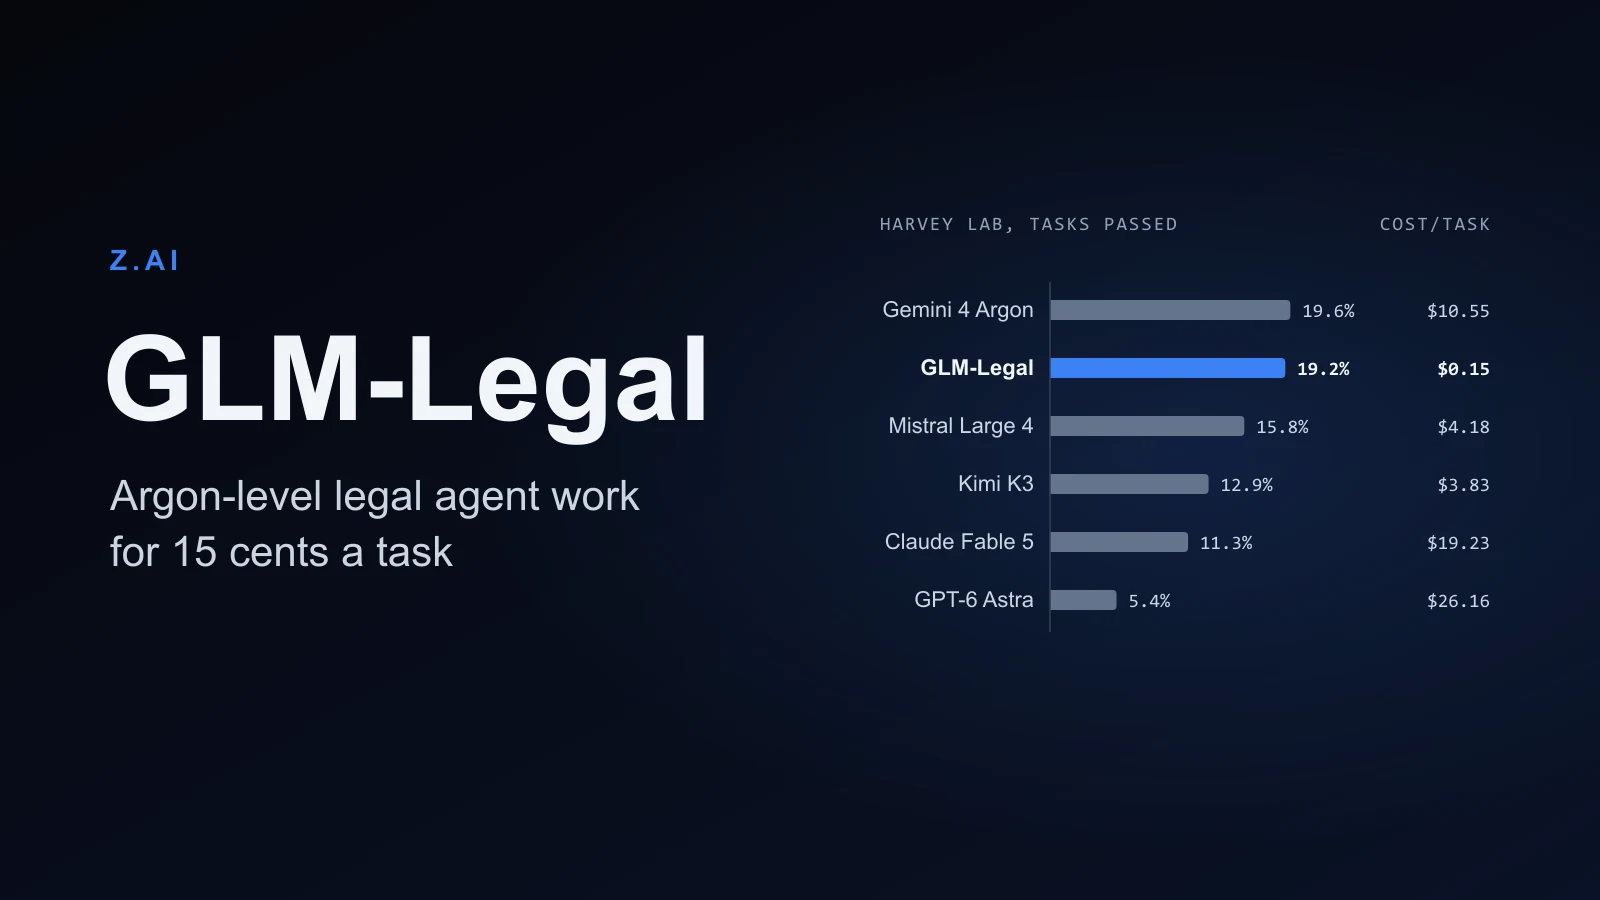
Z.ai, the company formerly known as Zhipu AI, announced GLM-Legal on Monday, a model trained for legal work from contract review to regulatory compliance. It starts from GLM-5.3-Flash, adds a mid-training pass on legal corpora and reinforcement learning across "tens of thousands of realistic legal environments", and turns evaluations by practicing lawyers into further training signal.
On Harvey's Legal Agent Benchmark, which tests an agent doing legal work with documents, spreadsheets, presentations and file-system tools, and passes a task only if every grading criterion passes, GLM-Legal scores 19.2%, up from 6.7% for its base model. Vals AI's independent leaderboard lists it seventh at 19.17%, just behind Google's Gemini 4 Argon at 19.58%, at $0.15 per task against $10.55 for Argon. Access is a gated beta for law firms, legal tech companies and in-house teams, and Z.ai hasn't published a price.
The leaderboard around it
Vals' table, updated on Monday, is led by the Muse Spark family, with Muse Spark 1.2 at 25.42%, and Wonder Full at 21.67%. Below GLM-Legal come Mistral Large 4 at 15.83%, Kimi K3 at 12.92%, Claude Fable 5 at 11.25% and GPT-6 Astra at 5.42%. Cost per task separates the field more than the scores do: GLM-Legal's 15 cents is the cheapest in the top 13, against $19.23 for Fable 5 and $26.16 for GPT-6 Astra. It is also among the slowest, at an average of 1 hour 12 minutes per task, three times the leader's 24 minutes.
The absolute numbers are low across the whole table because the grading is strict: two model judges score every task, and one missed criterion fails it. At 19%, roughly four tasks in five still go wrong somewhere, so a lawyer still has to review whatever these agents produce.
What firms will ask first
Z.ai hasn't said which jurisdictions the model covers, and its other legal claim, parity with frontier systems on PLawBench, is about Chinese legal consultation, case analysis and drafting. The LegalBench result also comes from Z.ai alone: 86.2 against 88.6 for Claude Fable 5, according to Z.ai's chart as reported by CellCog. GLM-Legal is not an open-weight release for now, so client documents would go to Z.ai's API, and as Artificial Lawyer put it, "lawyers will understandably want more information on where data goes." Z.ai says the model is also coming to AutoClaw, its desktop agent, without a date.
Sources and further reading
- Original publication
- Z.ai: GLM-Legal, advancing agentic legal intelligence
- Vals AI: Harvey's Legal Agent Benchmark leaderboard
- Artificial Lawyer: Chinese company launches legal-specific LLM
- Unite.AI: Z.ai unveils GLM-Legal, an agentic model for legal workflows
- CellCog: GLM-Legal, Z.ai's legal model, benchmarks checked
Share this news
Related Items
- NewsGoogle announces Gemini 4 Argon, its new frontier model, and gives it to cyber defenders firstArgon scores 77.9% on DeepSWE, against 74.2% for Claude Opus 5.5 and 74.1% for GPT-6 Astra, and can write up to 1 million tokens in one answer. It launches at $2 and $10 per million tokens, rising later to $4 and $20, once it reaches paid API customers and Google AI Ultra.
- NewsCopilot canvases turn agent work into custom interfacesGitHub shows how developers can build shared, interactive surfaces for planning and tracking work with agents.
- NewsReflection AI unveils Beam, a 501B open-weight model it will release under Apache 2.0The sparse mixture-of-experts model activates 23B parameters per token, reads up to 1M tokens and, by Reflection's own numbers, competes with GLM 5.2 on coding and agent work. The weights, technical report and quantized versions are due later in October; for now there is only an early access program.
Comments
Questions, corrections, or your own take are all welcome. Sign in with GitHub to join in.