Mistral AI
Mistral unveils Large 4, a 1-trillion-parameter model it will release with open weights this month
The mixture-of-experts model activates 49B parameters per token, reads text and images and, by Mistral's numbers, leads the open models from China on agentic coding. The API is in preview at $1.36 and $4.18 per million tokens, cyber defenders get a less restricted version first, and the weights are due October 27.
Share this news
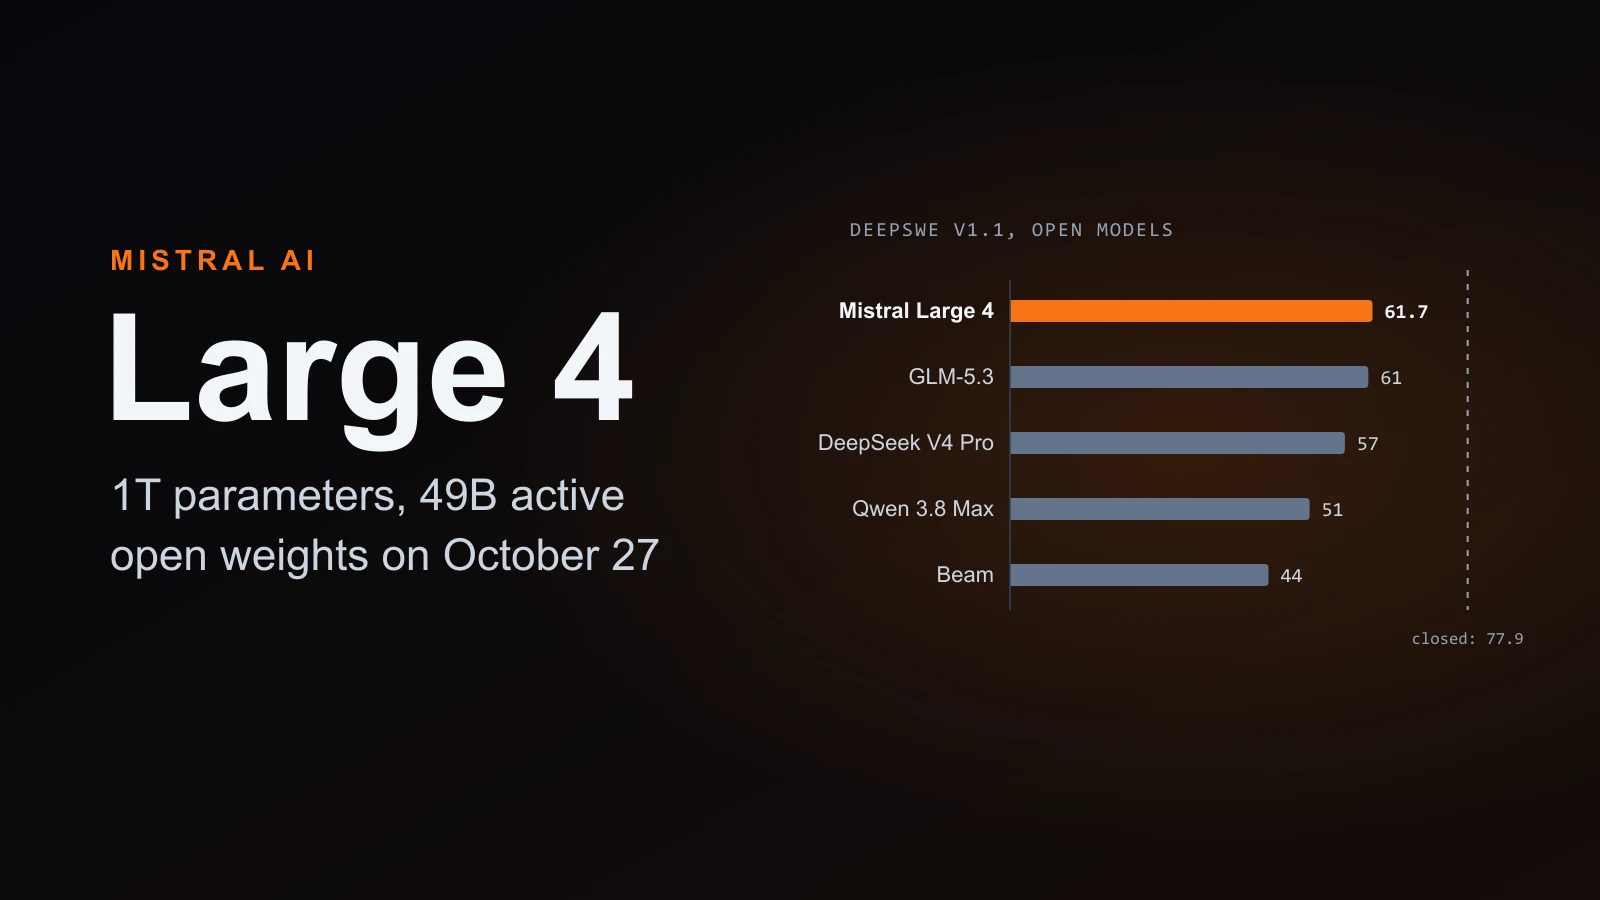
Mistral AI chief executive Arthur Mensch unveiled Mistral Large 4 on Tuesday at AI Everything in Abu Dhabi. The model has 1 trillion parameters, 49 billion of them active for each token, takes images as well as text, and was trained in more than 160 languages, including every official language of the European Union. Mistral trained it from scratch on 3,800 NVIDIA Grace Blackwell GPUs in its own European data centers.
A public preview is live in Mistral Studio at $1.36 per million input tokens and $4.18 per million output tokens. The weights follow at the end of the month, on October 27 according to VentureBeat and The Next Web. Mistral's post doesn't name the license, and VentureBeat reports a custom Mistral license for the weights, not a standard open-source one.
Where it lands
Mistral reports 61.7% on DeepSWE v1.1, the agentic coding benchmark. In the comparison published with the launch, that puts Large 4 ahead of Zhipu's GLM-5.3 at 61%, DeepSeek V4 Pro at 57% and Qwen 3.8 Max at 51%, and well ahead of Reflection's Beam, announced on Monday, at 44%. The closed frontier is still further out: Google reported 77.9% for Gemini 4 Argon last week. The other headline numbers are 67% on FinWorkBench, tied with DeepSeek V4 Pro, 82% on the AA Cyber Index for vulnerability reproduction, 93% on Cybench, 28.3% on Terminal Bench 4.0 and 42% on Dense200 visual grounding, a point above GPT-6 Astra by Mistral's count.
A cyber model first
The three-week preview goes first to "cybersecurity leaders, vetted partners, and state authorities", who get a version with reduced moderation and expanded cyber capabilities compared with the public API. Mistral pitches it as defense against attackers who jailbreak closed models, and pairs it with a sovereignty argument aimed at European companies and governments: they get guarantees against foreign access restrictions, because, in Mistral's words, they "should not depend on a provider that could switch off their tools at any moment."
What to check when the weights ship
Every number above comes from Mistral's own runs and stays provisional until outside teams test the released weights. Two details will decide how open the release really is. One is the license text, which Mistral hasn't published. The other is hardware: a trillion parameters take about a terabyte of memory even in FP8, which means a server with eight of NVIDIA's largest GPUs or more. That puts self-hosting within reach of the governments and large companies Mistral named as its first customers, far more than of individual developers.
Sources and further reading
- Original publication
- Mistral AI: Introducing Mistral Large 4
- VentureBeat: Mistral debuts Large 4 'Le Chonk', a 1-trillion-parameter model planned for open weights
- The Next Web: Europe's Mistral launches Large 4 to challenge China's lead in open AI models
- SiliconANGLE: Mistral launches Mistral Large 4 and details its AI roadmap
- AI News: Mistral AI launches Large 4 preview ahead of open-weight release
Share this news
Related Items
- NewsReflection AI unveils Beam, a 501B open-weight model it will release under Apache 2.0The sparse mixture-of-experts model activates 23B parameters per token, reads up to 1M tokens and, by Reflection's own numbers, competes with GLM 5.2 on coding and agent work. The weights, technical report and quantized versions are due later in October; for now there is only an early access program.
- NewsMeta releases Muse Spark Open, an 816B open-weight model built to run on two Mac StudiosThe mixture-of-experts model activates 42B of its 816B parameters per token, reads text, images, video and audio, and has a 1M-token context. Meta calls it the most capable US open-weight model, and its own table backs that up while still putting it behind GLM 5.3 and Kimi K3 on most agent and coding benchmarks.
- NewsGoogle announces Gemini 4 Argon, its new frontier model, and gives it to cyber defenders firstArgon scores 77.9% on DeepSWE, against 74.2% for Claude Opus 5.5 and 74.1% for GPT-6 Astra, and can write up to 1 million tokens in one answer. It launches at $2 and $10 per million tokens, rising later to $4 and $20, once it reaches paid API customers and Google AI Ultra.
Comments
Questions, corrections, or your own take are all welcome. Sign in with GitHub to join in.