DeepSeek
DeepSeek ships V4.1-Flash-1017 with MIT-licensed weights and opens paid Search and Fetch APIs
The minor update lifts DeepSeek's own Terminal-Bench 4.0 score from 31.2 to 42.3 with a 1M-token context window, and the new web tools cost $0.75 per 1,000 successful calls, free through server-side tools until October 31.
Share this news
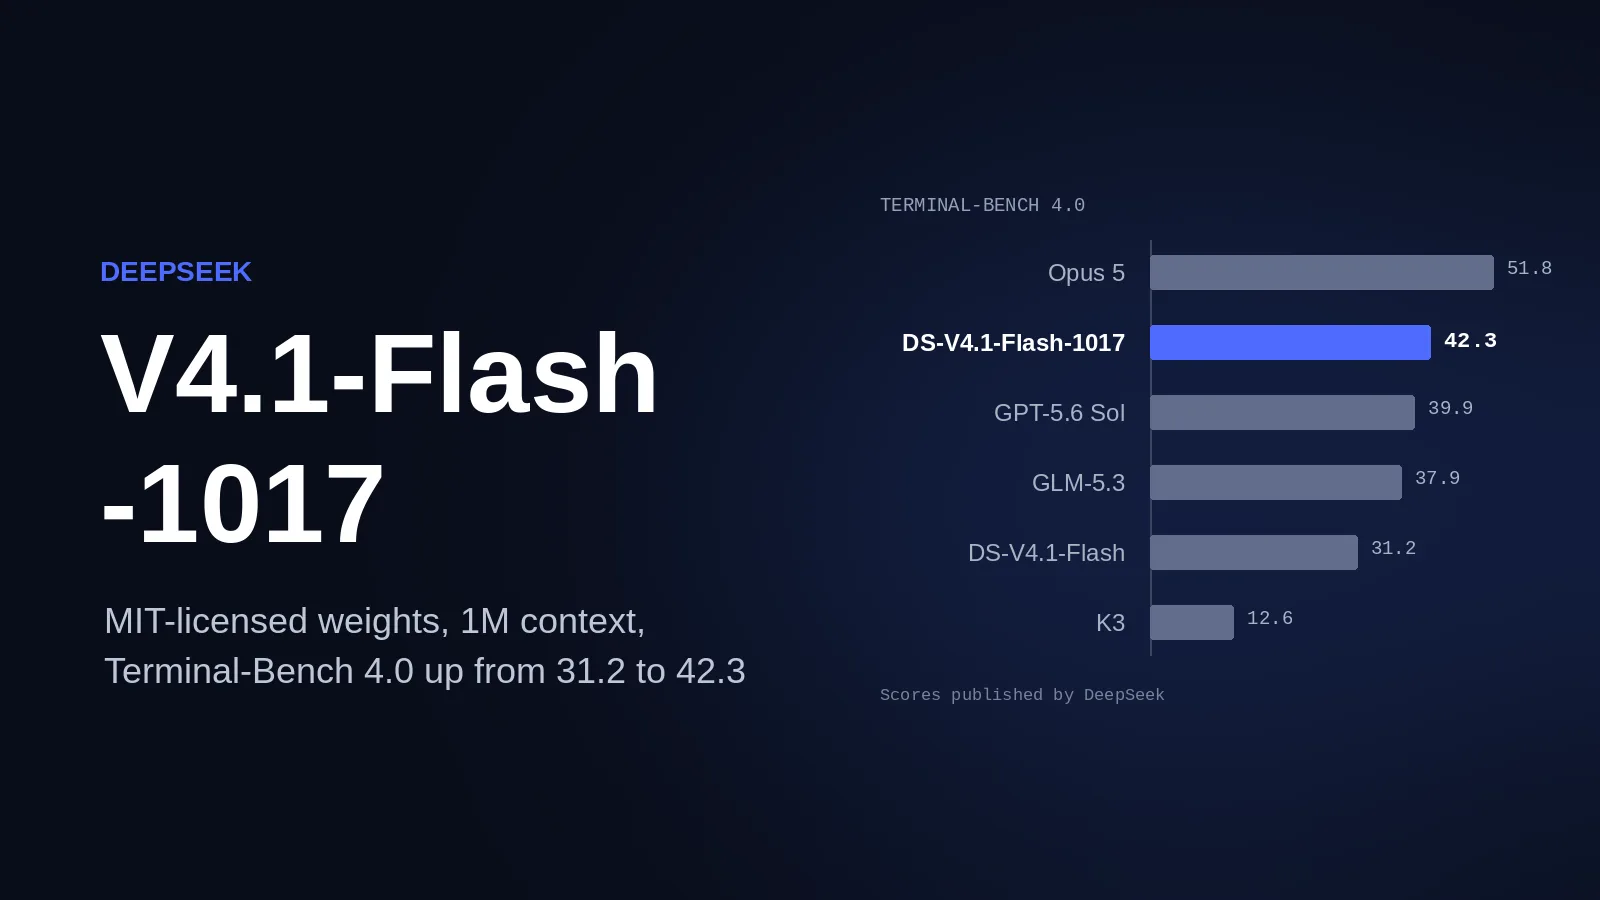
DeepSeek released DeepSeek-V4.1-Flash-1017, which its model card calls "a minor update to DeepSeek-V4.1-Flash" with "substantial improvements across reasoning, coding, agentic tasks, and visual benchmarks." The weights are on Hugging Face under the MIT License, and the card recommends a 1M-token context window and a max_tokens of at least 256K.
Alongside it, DeepSeek opened its Search and Fetch APIs to everyone. Each costs $0.75 per 1,000 successful requests, and per-request billing for server-side calls through DeepSeek Harness, Claude Code and Codex starts at 00:00 Beijing time on November 1 (16:00 UTC on October 31).
What changed in the model
DeepSeek says the update also cuts task execution time and output length, so agents finish faster and cheaper. On its own table, the model goes from 74.2 to 77.0 on DeepSWE v1.1 (Mini-SWE-V2 harness) and from 31.2 to 42.3 on Terminal-Bench 4.0 (Claude Code harness). Humanity's Last Exam without tools moves from 36.8 to 42.6.
The same table puts it ahead of GPT-5.6 Sol (73.0) and Opus 5 (74.0) on DeepSWE, but behind Opus 5 on most other rows, including Terminal-Bench (51.8) and Humanity's Last Exam (56.3). These are scores published by DeepSeek, not independent tests.
Running it yourself
The release has no Jinja chat template. Instead, an encoding folder holds a Python reference implementation of the prompt format, and DeepSeek published deepseek-recipe, a set of Rust libraries with Python bindings that convert Messages, Chat Completions and Responses API requests into DeepSeek V4 and V4.1 prompts. The card lists 763B parameters and recommends temperature 1.0 and top_p 1.0.
Through the API, the model is served as deepseek-flash. According to the pricing page, the older deepseek-v4-flash names still work but now route to this model, billed at the Flash price: $0.15 per million input tokens on a cache miss and $0.60 per million output tokens off-peak, double at peak hours.
The web tools
Search takes a query and returns ranked results; Fetch takes a URL and returns the page. Both use the same API key as the chat API. Failed requests, empty results and timeouts are not billed. Startup Fortune reports a limit of 5 requests per second per account for each endpoint, and notes that DeepSeek's privacy policy stores personal data in China, which matters if your queries are sensitive.
What to check in your stack
If you already point an agent at deepseek-flash or the legacy Flash names, you are now on this model without changing anything, so rerun your own evals before trusting the new numbers. If you use DeepSeek's server-side search through Claude Code or Codex, it is free only until October 31; after that, budget $0.75 per 1,000 calls for each of Search and Fetch.
Sources and further reading
Share this news
Related Items
- NewsMistral unveils Large 4, a 1-trillion-parameter model it will release with open weights this monthThe mixture-of-experts model activates 49B parameters per token, reads text and images and, by Mistral's numbers, leads the open models from China on agentic coding. The API is in preview at $1.36 and $4.18 per million tokens, cyber defenders get a less restricted version first, and the weights are due October 27.
- NewsMeta releases Muse Spark Open, an 816B open-weight model built to run on two Mac StudiosThe mixture-of-experts model activates 42B of its 816B parameters per token, reads text, images, video and audio, and has a 1M-token context. Meta calls it the most capable US open-weight model, and its own table backs that up while still putting it behind GLM 5.3 and Kimi K3 on most agent and coding benchmarks.
- NewsReflection AI unveils Beam, a 501B open-weight model it will release under Apache 2.0The sparse mixture-of-experts model activates 23B parameters per token, reads up to 1M tokens and, by Reflection's own numbers, competes with GLM 5.2 on coding and agent work. The weights, technical report and quantized versions are due later in October; for now there is only an early access program.
Comments
Questions, corrections, or your own take are all welcome. Sign in with GitHub to join in.